Dr. Joy Bose
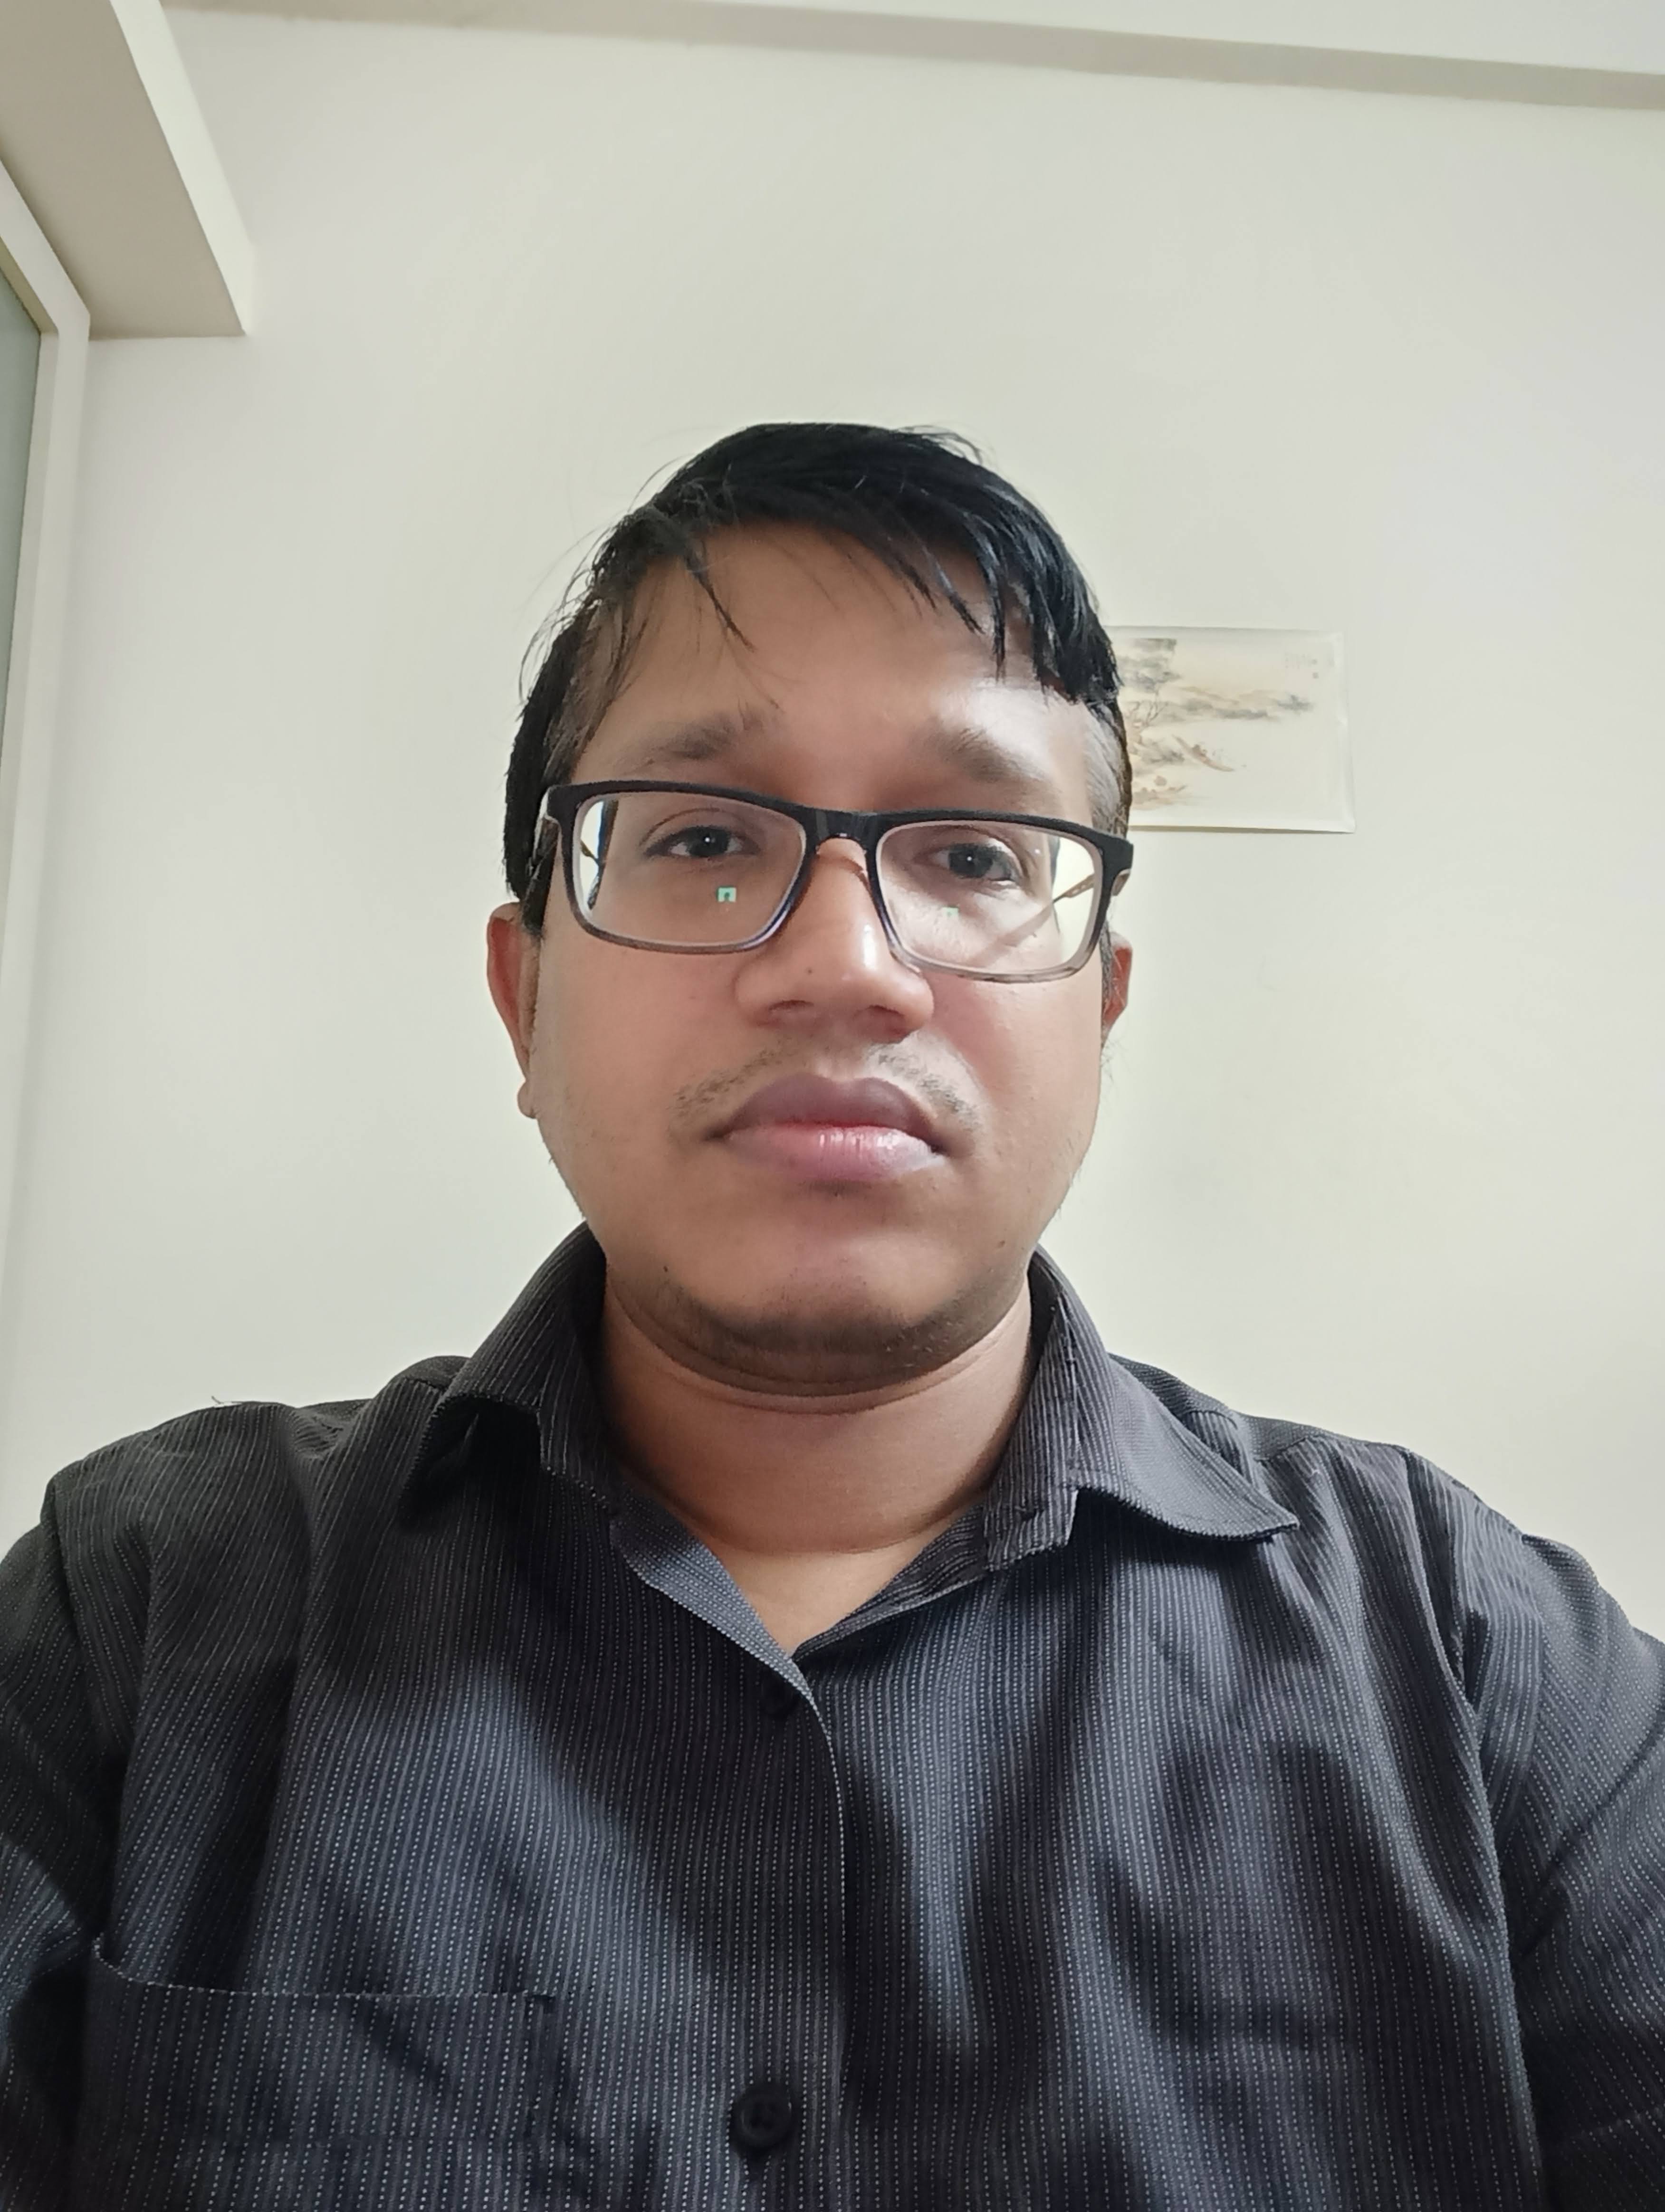
I am an AI researcher and director at Hexaware, Bengaluru, with 15+ years building production ML and GenAI systems across telecom, edtech, and browser intelligence. At Ericsson (2020 to 2026) I built RAG pipelines, LLM orchestration, knowledge graphs, and MCP-based agentic AI tools that were adopted by 1,000+ engineers across the BCSS division.
I hold a PhD in Computer Science from the University of Manchester (2007), where I worked on spiking neural networks and sequence learning under Steve Furber and Jon Shapiro. Since then I have worked at Samsung R&D, Microsoft (Edge team), and Ericsson, accumulating 8 granted US and European patents (20+ filed) and 20+ publications, with an h-index of 13. Latest peer-reviewed work includes papers at ICSME 2025, PROFES 2026, CODS 2026 and COMSNETS 2027 on topics related to neural networks, telecom RAG, LLM-based code review and hierarchical code knowledge graphs.
At Microsoft I built ML tools for browsers, at Samsung EEG-based emotion-sensitive web features and bias-detecting news systems, and at Ericsson LLM-based tools for telecom automation. I have always had a strong research bias.
Alongside my technical work I have pursued a parallel path into the sciences of mind. I hold an MSc in Psychology and Neuroscience of Mental Health from King's College London, and an LLM in International Business Law with a dissertation on AI ethics from Golden Gate University (Summa Cum Laude, GPA 4.0).
These interests shape both my research and my writing. I am the author of Building Consciousness: Buddhism, Neuroscience and Sentient AI, exploring what contemplative traditions and neuroscience reveal about machine intelligence, and Wearable Gadgets, Technology and Meditation, on the intersection of consumer technology and contemplative practice. I also write regularly on Medium about AI, consciousness, and the future of technology.
Selected research
Indian Philosophy: Concept by Concept (2026) · arXiv preprint
Ten core concepts, eleven schools, every claim grounded in a real citation
An interactive comparison of how Advaita Vedanta, Dvaita Vedanta, Vishishtadvaita, Achintya Bhedabheda, Buddhism, Jainism, Samkhya, Yoga, and Vaisheshika each answer the same questions about the self, ultimate reality, karma, suffering, and liberation, browsable either by concept (how schools differ on one idea) or by school (what one school says across all ideas). Built on darshana-graph, a text-grounded knowledge graph of 28,000+ typed relationships extracted from public-domain translations of the Upanishads, Brahma Sutras, Bhagavad Gita, and the Pali Canon. Every summary on every page cites a real passage in a real text, no claim is generated from background knowledge alone.
Browse the concepts | Darshana-graph (code + data) | Vada-simulator (multi-agent debate engine)
arXiv: 2606.18222 · Dataset on HuggingFace
Indus Script: A Falsification-Oriented Analysis (2026) · SSRN working paper
A machine built to distrust its own best result on the Indus Valley script
A computational study of the undeciphered Indus Valley script that tries to prove its own best finding wrong. A pattern that looked like real structure, knowing the two symbols before a gap helped predict what came next, showed up in two separately digitized copies of the ancient inscriptions. But once the test was redone so a repeated inscription couldn't pass just by recognizing a copy of itself, the pattern flipped and mostly disappeared. This paper claims no sign readings. A companion piece proposes a plain three-step test for judging any future claim to have cracked the script.
Read the project page | Code (GitHub) | Medium: I Built a Machine to Study the Mysterious Indus Valley Script
SSRN: 7436801 · Medium: How Would We Know If Someone Actually Cracked It?
Spikes, Order, and Memory (2026) · arXiv preprints
The spiking machine from my 2007 PhD, and why it keeps reappearing in transformer research
A plain-language walkthrough of a single research thread: how the spiking sequence machine I built at Manchester turned into four recent papers on transformers, associative memory, neuron dynamics, and sensorimotor coding. The through-line is that order, time, and memory are representational primitives, not metadata bolted on afterward. Covers the functional equivalence between a spiking Sparse Distributed Memory and the transformer (the Phase-Latency Isomorphism), a controlled teardown of rank-order N-of-M memory, a pendulum model of the neuron itself, and a spiking reinterpretation of the Thousand Brains architecture, with concrete ideas for making transformers better.
Read the walkthrough | Position paper: order, time and memory in sequence models | STSM code | All repos
arXiv: 2605.00662 · 2607.02967 · 2507.22146 · 2605.22206
Computational Justice (2026) · arXiv preprints and SSRN
From judicial process mining to verified legal AI: the complete research programme
A full map of my legal-tech work, from diagnosing why Indian courts are slow to building AI that has to prove its reasoning before it can be trusted. Covers the STRIDE bottleneck analysis of 2.45 million writ petitions, the IMLJD and RTI-Bench datasets on matrimonial litigation and RTI decisions, the Falkor-IRAC graph-constrained reasoning system with its Verifier Agent, and NyayaSaar-LoRA for plain-language legal AI, and how all four layers connect into a single programme aimed at making the justice system more legible and more accessible.
Read the full programme | Falkor-IRAC (arXiv) | SSRN bottleneck paper
IMLJD: 2605.19346 · RTI-Bench: 2605.16843 · NyayaSaar-LoRA · Code and datasets
Deep Hough for Curves (2026) · paper on Zenodo
How I taught a neural network to find curves by counting votes
A plain-language, 5-minute explainer of my paper on generalizing the Deep Hough Transform beyond straight lines: why the obvious approach needs 4 GB of memory, and how a two-round election gets it down to 236 KB.
Read the explainer | Code | Paper doi:10.5281/zenodo.21424983
More
- Building Consciousness (book, 2026). Argues that consciousness is not computation: it needs temporal integration, embodied coupling, and affective grounding that current AI systems lack. Read free online | Kindle | Paperback | DOI
- AI for Indian Legal Practice (book, 2026). Graph-constrained legal reasoning, hallucination and verification, and RAG tools for lawyers, drawing on the IMLJD and RTI-Bench datasets. Free PDF | Zenodo
- Buddhist Visualizations (2026). Sixty interactive visualizations of classical Buddhist ideas, each tagged as classical, a modern rendering, or a modern analogy. Explore
- Karaka: Sanskrit Grammar as a Calling Convention (2026). Panini's six semantic roles as an order-free way to bind arguments in logic programming, including where the idea stops working. Interactive explainer | Code and paper | Medium
- Toward an Indian Sovereign AI Strategy (2026). A comparative policy analysis of China's AI governance architecture, with a ten-pillar framework for India. SSRN | Medium: China Has DeepSeek, India Has Sarvam | Medium: Why DeepSeek Emerged in China Before India
- Navigating the AI Job Market (book, 2026). A guide for Indian AI and data science professionals on GCCs, layoffs, interviews, offers, and independent work. Free PDF | Paperback | DOI
To know more about my work, browse the links on the left.
Connect with me: